One of the first things you learn when building a React application is how to display data on a page. You can create components, pass props, manage state, and build an interface that looks exactly how you want.
But real applications rarely rely on data that you manually enter into your code.
A dashboard needs information from a backend. A product page needs to retrieve products from a database. A lending application needs to display customer details, loan applications, repayment records, and transaction histories.
That is where APIs come in.
Working with REST APIs is a fundamental part of frontend development, but there is a difference between getting an API request to work and integrating it properly into an application.
In this article, I want to walk through how I approach REST API integration in React, from making a simple request to handling the situations that can make an application unreliable if they are overlooked.
1. Understanding the relationship between React and REST APIs
Before writing code, it helps to understand what happens when a React application communicates with a backend.
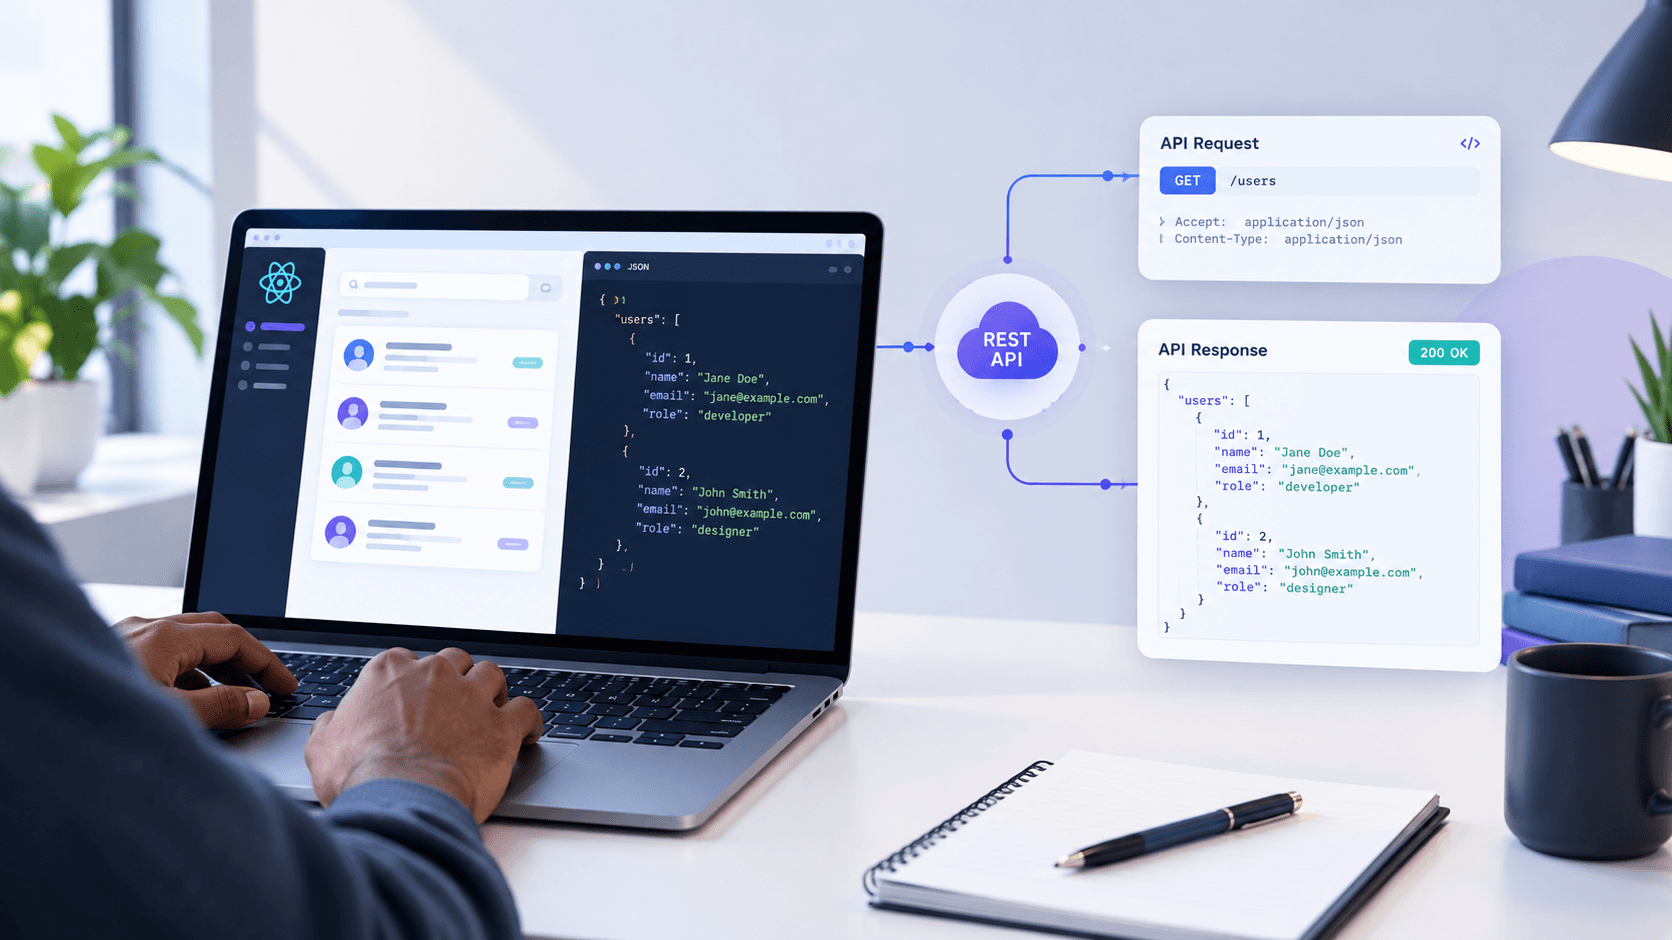
A typical interaction looks something like this:
- A user opens a page in the application.
- React renders the interface.
- The application sends an HTTP request to a backend API.
- The backend processes the request and retrieves or updates data.
- The API returns a response, often in JSON format.
- React uses the response to update the interface.
For example, a dashboard might request a list of customers:
GET /api/customers
The backend could return:
[
  {
    "id": 1,
    "name": "Jane Mwende",
    "email": "jane@example.com"
  },
  {
    "id": 2,
    "name": "Peter Kamau",
    "email": "peter@example.com"
  }
]
React then takes that response and renders the information.
The important thing to remember is that React handles the user interface, while the backend is responsible for the data and business rules it owns.
Keeping that distinction clear helps prevent frontend components from becoming responsible for things they should not control.
2. Making your first API request
JavaScript provides the Fetch API, which is sufficient for many straightforward API requests.
Here is a basic example of retrieving customers:
import { useEffect, useState } from "react";

type Customer = {
  id: number;
  name: string;
  email: string;
};

export default function Customers() {
  const [customers, setCustomers] =
    useState<Customer[]>([]);

  useEffect(() => {
    async function fetchCustomers() {
      const response = await fetch(
        "/api/customers"
      );

      if (!response.ok) {
        throw new Error("Failed to fetch customers");
      }

      const data: Customer[] = await response.json();
      setCustomers(data);
    }

    fetchCustomers().catch(console.error);
  }, []);

  return (
    <ul>
      {customers.map((customer) => (
        <li key={customer.id}>
          {customer.name} — {customer.email}
        </li>
      ))}
    </ul>
  );
}
This example demonstrates the basic process:
- Define the expected data structure.
- Make the request.
- Check whether the HTTP response indicates success.
- Parse the JSON response.
- Store the data in React state.
- Render the results.
However, I would not consider this a complete production-ready implementation.
What happens if the internet connection fails? What does the user see while the request is running? What if the server returns an error? What if the component unmounts before the request finishes?
These are not unusual situations. They are part of building applications that work outside a development environment.
There is also an important distinction in the example above: fetch() generally rejects for network failures, but it does not automatically throw an exception for HTTP errors such as 404 Not Found or 500 Internal Server Error. That is why checking response.ok matters.
3. Handle loading, error, empty, and success states
One lesson that becomes more apparent as applications grow is that displaying data is only one part of the user experience.
Consider a customer list. There are several possible states:
- Loading: The request is still in progress.
- Error: The request failed.
- Empty: The request succeeded, but no customers were returned.
- Success: Customers are available to display.
If you account for only the success state, users may be left staring at an empty page when something goes wrong.
Here is a more complete implementation:
import { useEffect, useState } from "react";

type Customer = {
  id: number;
  name: string;
  email: string;
};

export default function Customers() {
  const [customers, setCustomers] =
    useState<Customer[]>([]);

  const [loading, setLoading] = useState(true);
  const [error, setError] = useState<string | null>(
    null
  );

  useEffect(() => {
    const controller = new AbortController();

    async function fetchCustomers() {
      try {
        setLoading(true);
        setError(null);

        const response = await fetch(
          "/api/customers",
          { signal: controller.signal }
        );

        if (!response.ok) {
          throw new Error(
            `Request failed: ${response.status}`
          );
        }

        const data: Customer[] = await response.json();

        setCustomers(data);
      } catch (err) {
        if (
          err instanceof Error &&
          err.name === "AbortError"
        ) {
          return;
        }

        setError(
          "Unable to load customers. Please try again."
        );
      } finally {
        if (!controller.signal.aborted) {
          setLoading(false);
        }
      }
    }

    void fetchCustomers();

    return () => controller.abort();
  }, []);

  if (loading) {
    return <p>Loading customers...</p>;
  }

  if (error) {
    return (
      <div>
        <p role="alert">{error}</p>
      </div>
    );
  }

  if (customers.length === 0) {
    return <p>No customers found.</p>;
  }

  return (
    <ul>
      {customers.map((customer) => (
        <li key={customer.id}>
          <strong>{customer.name}</strong>
          <span> — {customer.email}</span>
        </li>
      ))}
    </ul>
  );
}
This version introduces AbortController, which allows the request to be cancelled when the component is cleaned up.
The example also makes the error message suitable for users rather than exposing raw technical details.
In a larger application, I would consider adding a retry action, a more informative empty state, and a reusable loading indicator.
The goal is not to make every component complicated. It is to make sure the interface communicates what is happening.
4. Separate API logic from UI components
As an application grows, putting every API request directly inside a component becomes difficult to maintain.
Imagine having several pages that retrieve customers. If each page contains its own request logic, you may end up repeating URLs, error handling, headers, and response parsing.
A better approach is to separate API communication from the components that display the results.
For example, a project might use this structure:
src/
├── components/
│   ├── Button.tsx
│   └── LoadingState.tsx
├── features/
│   └── customers/
│       ├── CustomersPage.tsx
│       ├── CustomerList.tsx
│       └── useCustomers.ts
├── services/
│   └── customerService.ts
├── types/
│   └── customer.ts
└── App.tsx
This is only one possible structure. The right arrangement depends on the size and needs of the project.
The principle is more important than the exact folder names: API communication, business-specific behaviour, and presentation should have clear responsibilities.
Define your data types
For example, create a customer.ts file:
export type Customer = {
  id: number;
  name: string;
  email: string;
};
Create a customer service
In customerService.ts:
import type { Customer } from "../types/customer";

export async function getCustomers(
  signal?: AbortSignal
): Promise<Customer[]> {
  const response = await fetch("/api/customers", {
    signal,
  });

  if (!response.ok) {
    throw new Error(
      `Failed to load customers: ${response.status}`
    );
  }

  return response.json() as Promise<Customer[]>;
}
Now the component can focus on the interface rather than the details of the request.
There is one important TypeScript caveat here. The return type tells TypeScript what the application expects, but it does not prove that the backend actually returned that structure. Runtime validation is needed when you must verify untrusted response data.
We will return to that distinction shortly.
Separating the service also makes it easier to update the API endpoint or request behaviour without editing every component that uses it.
5. Avoid repeating request configuration
As more endpoints are added, applications often need the same configuration for each request:
- A base URL.
- Common headers.
- Authentication credentials where required.
- Consistent handling of HTTP errors.
One approach is to create a small reusable API client.
For example, in a Vite application, you can define a public API base URL in an environment file:
VITE_API_BASE_URL=https://api.example.com
Then use it in a shared client:
const API_BASE_URL =
  import.meta.env.VITE_API_BASE_URL;

export async function apiRequest<T>(
  path: string,
  options: RequestInit = {}
): Promise<T> {
  const response = await fetch(
    `${API_BASE_URL}${path}`,
    options
  );

  if (!response.ok) {
    throw new Error(
      `API request failed: ${response.status}`
    );
  }

  return response.json() as Promise<T>;
}
A service can now use the shared client:
import { apiRequest } from "./apiClient";
import type { Customer } from "../types/customer";

export function getCustomers() {
  return apiRequest<Customer[]>("/api/customers");
}
This is a useful starting point, but the client is intentionally minimal. A production implementation should account for endpoints that return no content, such as 204 No Content, and should define how different error responses are handled.
It is also important to remember that VITE_ environment variables are exposed to browser-side code when bundled. They are appropriate for public configuration, such as an API URL, but never put passwords, private API keys, database credentials, or other secrets in frontend environment variables.
Environment variables help separate configuration from source code. They do not make browser-side values secret.
6. Understand authentication and protected endpoints
Some APIs allow public access, while others require a user to be authenticated.
For example, a public endpoint might return a list of available products. A protected endpoint might return the details of the currently signed-in user's account.
The frontend needs to follow the authentication approach established by the backend.
With cookie-based authentication, a request to an API on another origin might look like this:
const response = await fetch(
  "https://api.example.com/api/profile",
  {
    credentials: "include",
  }
);
This tells the browser to include credentials such as eligible cookies with the request. Cross-origin cookie authentication also requires appropriate server-side CORS and cookie configuration.
Another architecture may use a bearer token:
const response = await fetch(
  "https://api.example.com/api/profile",
  {
    headers: {
      Authorization: `Bearer ${accessToken}`,
    },
  }
);
The token must come from the application's established authentication flow. It should not be hardcoded into the component.
Authentication is not simply a matter of attaching a header. You also need to think about expired sessions, 401 Unauthorized responses, insufficient permissions, logout behaviour, and what happens when a user's access changes.
Where the architecture permits it, server-managed HttpOnly cookies can reduce the risk of tokens being read by JavaScript. They still require appropriate protections against cross-site request forgery and other relevant threats.
Most importantly, hiding a button in React does not secure an operation. The backend must independently enforce authentication, authorization, and business rules.
7. Handle changing data without race conditions
A subtle problem can occur when API requests depend on user input.
Imagine a page with a search box. A user types:
reareactreact developer
Each change triggers a request.
Network requests do not necessarily finish in the order they were started. The response for rea might arrive after the response for react developer, causing older results to replace newer ones.
This is a race condition.
For a search interface, you can combine cancellation with a short debounce delay. Debouncing avoids sending a request for every keystroke, while cancellation helps prevent outdated requests from updating the interface.
Here is a simplified pattern:
import { useEffect, useState } from "react";

type SearchResult = {
  id: number;
  title: string;
};

export function SearchResults({
  query,
}: {
  query: string;
}) {
  const [results, setResults] =
    useState<SearchResult[]>([]);

  const [error, setError] = useState<string | null>(
    null
  );

  useEffect(() => {
    const controller = new AbortController();

    const timeoutId = window.setTimeout(async () => {
      try {
        setError(null);

        const response = await fetch(
          `/api/search?q=${encodeURIComponent(query)}`,
          { signal: controller.signal }
        );

        if (!response.ok) {
          throw new Error("Search failed");
        }

        const data: SearchResult[] =
          await response.json();

        setResults(data);
      } catch (err) {
        if (
          err instanceof Error &&
          err.name === "AbortError"
        ) {
          return;
        }

        setError("Unable to complete the search.");
      }
    }, 300);

    return () => {
      window.clearTimeout(timeoutId);
      controller.abort();
    };
  }, [query]);

  if (error) {
    return <p role="alert">{error}</p>;
  }

  return (
    <ul>
      {results.map((result) => (
        <li key={result.id}>{result.title}</li>
      ))}
    </ul>
  );
}
This example keeps the implementation small enough to understand. A complete search interface would also track loading state, clear or retain results intentionally, and decide what to display when the query is empty.
For more complex interactions, it is worth considering a dedicated data-fetching library rather than implementing every behaviour yourself.
8. Work with pagination, filtering, and sorting
Real-world applications rarely display every record at once.
A customer management system might have thousands of customers. A loan management dashboard might contain hundreds of applications. Fetching everything in one request can increase response times and consume unnecessary bandwidth.
Pagination allows the frontend to request a smaller subset of records.
For example:
GET /api/customers?page=1&pageSize=20
Filtering and sorting can also be represented in query parameters:
GET /api/customers?status=active&page=1&pageSize=20&sortBy=name
The exact parameter names depend on the backend API contract.
A paginated response might look like this:
{
  "items": [
    {
      "id": 1,
      "name": "Jane Mwende",
      "email": "jane@example.com"
    }
  ],
  "page": 1,
  "pageSize": 20,
  "totalItems": 156
}
The frontend can use the response metadata to display pagination controls and determine whether more pages are available.
When integrating an existing backend, do not assume it follows this exact structure. Confirm the endpoint's request parameters, response format, sorting rules, and filtering behaviour first.
That small step can save a surprising amount of rework.
9. Understand TypeScript types versus runtime validation
TypeScript is extremely useful when working with APIs because it helps describe the data your components expect.
For example:
type LoanApplication = {
  id: string;
  applicantName: string;
  amount: number;
  status: "pending" | "approved" | "rejected";
};
This makes the expected shape of a loan application clear and helps catch mistakes when writing code.
However, TypeScript types are removed during compilation. They do not validate JSON received over a network.
If an API returns this:
{
  "id": "loan-123",
  "applicantName": "Jane Mwende",
  "amount": "50000",
  "status": "processing"
}
the response does not match the declared type: amount is a string, and processing is not one of the expected statuses.
A type assertion such as response.json() as LoanApplication does not fix the data. It simply tells the compiler to trust the developer.
For critical integrations, consider validating API responses at runtime with a schema-validation library such as Zod. This is particularly useful when backend responses are outside your direct control or when malformed data could cause serious problems.
The broader lesson is that TypeScript helps you reason about expected data; runtime validation checks whether the actual data meets those expectations.
Both can be useful, but they solve different problems.
10. Know when to use a data-fetching library
For a small application, Fetch API and React hooks may be all you need.
As an application grows, however, data fetching can become more complicated. You may need caching, background refreshes, request deduplication, pagination, retries, or automatic refetching after a mutation.
This is where tools such as TanStack Query or SWR can help.
They provide established patterns for managing server state instead of requiring you to build every feature yourself.
For example, with TanStack Query, a customer query might look like this:
import { useQuery } from "@tanstack/react-query";
import { getCustomers } from "../services/customerService";

export function CustomersPage() {
  const {
    data: customers,
    isPending,
    isError,
    error,
  } = useQuery({
    queryKey: ["customers"],
    queryFn: () => getCustomers(),
  });

  if (isPending) {
    return <p>Loading customers...</p>;
  }

  if (isError) {
    return <p>{error.message}</p>;
  }

  if (customers.length === 0) {
    return <p>No customers found.</p>;
  }

  return (
    <ul>
      {customers.map((customer) => (
        <li key={customer.id}>
          {customer.name}
        </li>
      ))}
    </ul>
  );
}
This assumes the application has already configured a QueryClientProvider and that getCustomers() returns the expected customer array or throws on failure.
The benefit is not that the code is automatically better because a library is involved. It is that common server-state problems can be handled using well-established mechanisms.
I would not introduce a data-fetching library just to make one simple request. But when several screens depend on shared data and caching or refetching becomes difficult to manage, it is worth evaluating.
11. Common mistakes to avoid
After understanding the main patterns, there are a few mistakes worth watching for when integrating APIs into React applications.
Putting everything inside components. Components become difficult to maintain when presentation, request construction, authentication, error handling, and data transformation are all mixed together.
Ignoring HTTP errors. A request can receive a 404 or 500 response without causing fetch() to reject. Always handle the response status appropriately.
Assuming the API always returns valid data. Backend changes, unexpected responses, and incorrect assumptions can break the frontend. Use types for development and runtime validation where needed.
Hardcoding API URLs everywhere. A central configuration makes it easier to maintain development, testing, and production environments.
Exposing secrets in frontend code. Anything shipped to the browser should be treated as accessible to users. Private credentials belong on the server.
Making unnecessary requests. Repeated fetching can slow down an interface and place avoidable load on the backend. Consider pagination, debouncing, caching, and sensible refetch policies.
Showing technical errors directly to users. Logs should help developers investigate failures, while the interface should communicate the problem in language users can understand.
Failing to check the backend contract. Confirm expected parameters, response shapes, status codes, authentication requirements, and error formats before implementing an integration.
None of these issues necessarily appears in a basic tutorial. They become important when the application starts serving real users and handling real data.
12. How I approach API integration in a real project
When working on a feature that depends on a backend, I find it useful to work through a consistent set of questions before writing too much code.
First, I understand the endpoint. What does it return? Which parameters are required? What happens when the request fails? Does it require authentication?
Next, I define the data structures the frontend needs. This gives the implementation a clearer contract and helps me understand how the backend response maps to the interface.
Then I decide where the API logic belongs. For a small feature, a simple service function may be sufficient. For a larger feature, I may also need a custom hook or a server-state library.
After that, I build the UI around the different states, not just the successful response. Loading, empty, error, and success states should all have an intentional design.
Finally, I test the less obvious situations: an unavailable backend, an empty response, invalid input, expired authentication, a slow connection, and data that changes while the user is interacting with the page.
This approach is useful because it keeps the implementation focused on the actual requirements rather than adding complexity before it is needed.
It also makes collaboration with backend developers easier. When both sides understand the API contract, it becomes simpler to identify whether a problem comes from the request, the response, the business logic, or the presentation layer.
Final thoughts
Integrating REST APIs is one of those skills that becomes more important as you move from building static interfaces to building complete applications.
The initial request is usually straightforward. The real work is making sure the application behaves predictably when requests fail, data changes, users search through large datasets, or authentication expires.
My main takeaway is this: do not treat API integration as a small task that ends when the data appears on the screen. Treat it as part of the application's architecture and user experience.
Start with the simplest solution that meets your requirements. Separate responsibilities when it improves maintainability. Handle errors intentionally, understand the data contract, and introduce additional tools when they solve a real problem.
Those habits will take you much further than memorising a particular API library.
And as with most areas of frontend development, the goal is not to write the most complicated code. It is to build something that works reliably, remains understandable, and can be improved as the application grows.